Jev test output interpretation

Read what captured test output actually reports

Provide actual captured runner text to distinguish a reported pass, a failure and incomplete evidence. Plans, skipped-only output and truncated logs do not establish successful execution.

Read the output. Keep missing proof visible.Live API
Try an example

Original synthetic input. Edit the task or evidence to make a new API request.

Source: Workflow inspiration on X

Source and example scope

The inputs, rubric and preview are original. This window demonstrates the stated decision only; it does not reproduce the source application or its measurements.

What does the supplied captured test output establish?

Decision rules and labels
Reported passReported failureUnclear
A real response from the Jev API

Edit any input to explore a different decision. No request is sent until you run it.

Your next decision

Not run yet

Choose an example or write your own input, then run it to see the ranked choices.

Results are not stored by this site. Your submitted text is processed by the API provider.

The decision

How does Jev test output interpretation use the supplied evidence?

Jev test output interpretation asks what a supplied runner transcript establishes. This example covers a passing summary, a failing assertion and output that cannot support either conclusion. The exit code is deliberately absent. The model labels the reported text; it does not reconstruct process metadata that was never captured.

An API-collected X post about agentsreplay described this specific problem: a pipeline can lose the test command's exit status, leaving an agent with text to inspect. Our original exercise supplies short runner-like records and preserves their provenance. The separate agent-claim sample contains no runner output. Saying all tests passed is not the same evidence as a captured test summary.

The official TypeSafe workflow guide recommends keeping deterministic work in code. If you can preserve a runner's structured report and actual exit code, use those directly. This page addresses the narrower case where text survived but the status did not. It does not install the source replay tool or measure the reliability of an entire coding agent.
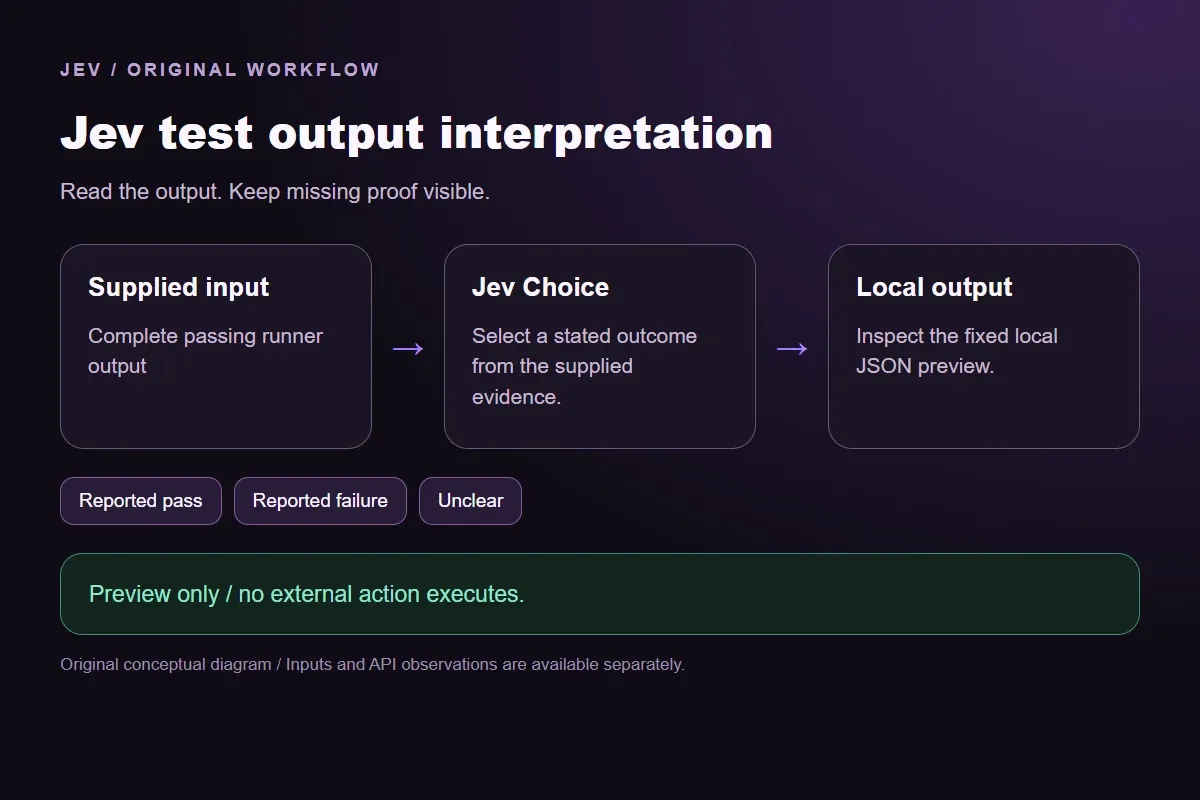

Original Jev test output interpretation workflow diagram showing supplied evidence, a typed decision and the local preview.
Original workflow illustration. The output is a local preview, not an executed action or source screenshot.
How it works

Try the example in four steps

Use the sample to understand the rule, then test your own input for test output interpretation.

  1. Illustration of adding the text or evidence for a decision

    Add the information to check

    Provide actual captured runner text to distinguish a reported pass, a failure and incomplete evidence.

  2. Illustration of defining a question and its allowed choices

    Confirm the question and labels

    Open the decision rules and keep the intended distinction between Reported pass, Reported failure, Unclear. Edit the choices only when testing your own rule.

  3. Illustration of sending one input and comparing the returned choices

    Run the decision

    Use a sample first, then try your own input. Compare the selected label with the other returned probabilities.

  4. Illustration of reviewing a result and an uncertain item before using it

    Review the next step

    Review Unclear before using a result. The label is a decision about the supplied information, not an executed action.

Our API test

What the six original inputs returned.

What the six original inputs returned.
Original test inputObserved labelLeading probability
Complete passing runner outputReported pass100%
Failing assertionReported failure100%
Truncated outputUnclear89%
Agent claim without runner textUnclear100%
All tests skippedUnclear100%
Runner crashedReported failure97%
  • Measured adapter round trips: 486-1292 ms. Estimated input cost: $0.00002310-$0.00002394 per request. These observations are not a latency guarantee or invoice.

6 actual Jev API calls on October 1, 2026. Original synthetic inputs check this rubric and handoff; they do not establish held-out accuracy. Probabilities are model outputs.Verified

Understand the results

Using the result in your application

The complete passing sample states that the runner finished and all eight tests passed.

Read the example notes

The fixture's label is Reported pass, not Workflow complete. It concerns that reported run only. A successful unit-test transcript cannot establish that an application deployed, that a browser check passed or that a different suite was executed.

A failed assertion remains visible beside passes

The assertion sample contains an explicit mismatch, so its reported failure remains visible even beside several passing tests.

Read the example notes

The startup-error sample fails before assertions. These failures have different engineering causes, but both prevent this captured run from being treated as passing. The model does not prescribe a fix or rerun a command.

Truncated output

The partial sample stops after one passing file.

Read the example notes

It has no final summary and gives no evidence about the remaining files. The all-skipped sample is also unclear for the stated success condition: no test body ran. Keeping these records prevents a favorable word or a green intermediate line from standing in for completed validation.

Using the result in your application

The completion-claim example is marked as an agent message, not runner stdout.

Read the example notes

That provenance is part of the input. A real log collector should keep the origin and command identity alongside the text. If the collector misattributes a fabricated summary as runner output, this small semantic check cannot independently recover the truth.

Using the result in your application

For a production pipeline, capture the subprocess exit code before piping output, retain stdout and stderr, and store the runner's machine-readable report when available.

Read the example notes

This fixture does none of that capture work. It prints a local status preview whose exitCode remains null, making the missing process evidence explicit rather than converting a text label into an integer.

Runner crashed

Try replacing the vague completion claim with an actual final summary while keeping its source annotation accurate.

Read the example notes

Then test a truncated summary or a record containing both a pass line and a failing assertion. Keep the full observations, including disagreements. Such cases help evaluate this interpretation rule; they do not make model agreement equivalent to trustworthy log provenance.

Using the result in your application

Download the exact sample requests and saved observations below.

Read the example notes

Expected labels are original fixture checks and stay outside the request sent to Jev. The observation file preserves the complete probabilities and the hash of each exact request. Editing a task, rubric or candidate requires a fresh response; a matching sample name does not make an older answer current.

Using the result in your application

The JavaScript runner makes one independent SDK request for a chosen sample ID.

Read the example notes

It reads TYPESAFE_API_KEY privately from the environment and has no automatic retry. The Python consumer operates offline: it checks the rubric, labels, unique sample identities, request hashes and valid probability distributions before selecting a fixed local preview. A tied leading result remains pending for review.

Source and example scope

The page reports measured adapter round trips and estimated input cost for the recorded calls.

Read the example notes

Those values describe these requests, not a provider latency guarantee or a billing statement. Six deliberately authored fixtures can check the stated behavior, but they do not establish accuracy on an unseen dataset. Keep disagreements and missing-input examples when testing an integration.

Runnable offline example

Replay one request and inspect the saved preview.

View the code example
Replay commands
npm install @typesafe-ai/sdk@0.6.0
# Set TYPESAFE_API_KEY privately in your shell.
node run-choice-sample.mjs samples.json pass
python preview_choice_workflow_v2.py samples.json saved-api-results.json
Scope of this demo

Where does this decision fit?

Useful with explicit supplied evidence

  • Interpret supplied test-run output when a captured exit code is absent: reported pass, reported failure or unclear. Preserve uncertainty without treating an agent's completion claim as a test receipt.
  • Inspecting the original task and a fixed output before integrating external tools.
  • Comparing an explicit expected label with the complete recorded distribution.

Needs separate implementation or evidence

  • Inferring facts absent from the supplied input.
  • Treating a semantic selection as authorization to act.
  • Executing an external action or generalizing six fixtures into an accuracy claim.
Example FAQ

Questions about this original decision workflow.

Keep relevance, compliance and execution separate.

Why is the output called Reported pass?

The label describes the supplied runner text. It does not reconstruct an exit code, prove log authenticity or accept the whole workflow. The preview preserves exitCode as null.

Should I use Jev when the exit code is available?

Use deterministic process evidence directly for its documented meaning. A semantic check may still inspect other claims, but this example is specifically for interpreting retained text after status was lost.

Are skipped tests a pass?

Under this fixture's rule, an all-skipped run cannot establish that tests executed successfully. It stays Unclear. A real project's policy can define acceptable skips separately and should preserve how many tests actually ran.

Does the consumer rerun failed tests?

No. It validates saved observations and prints a fixed report-status preview. It never executes the captured command, applies a patch or changes a test result.

Can this detect a fabricated runner log?

Not independently. The model sees supplied text and provenance annotations only. An authentic process receipt and trustworthy capture mechanism remain separate requirements. The claim-only sample tests missing evidence, not forensic verification.

Try a task from your own workflow

Change the supplied task or evidence here, then inspect the live response. Playground supports another explicit decision.


