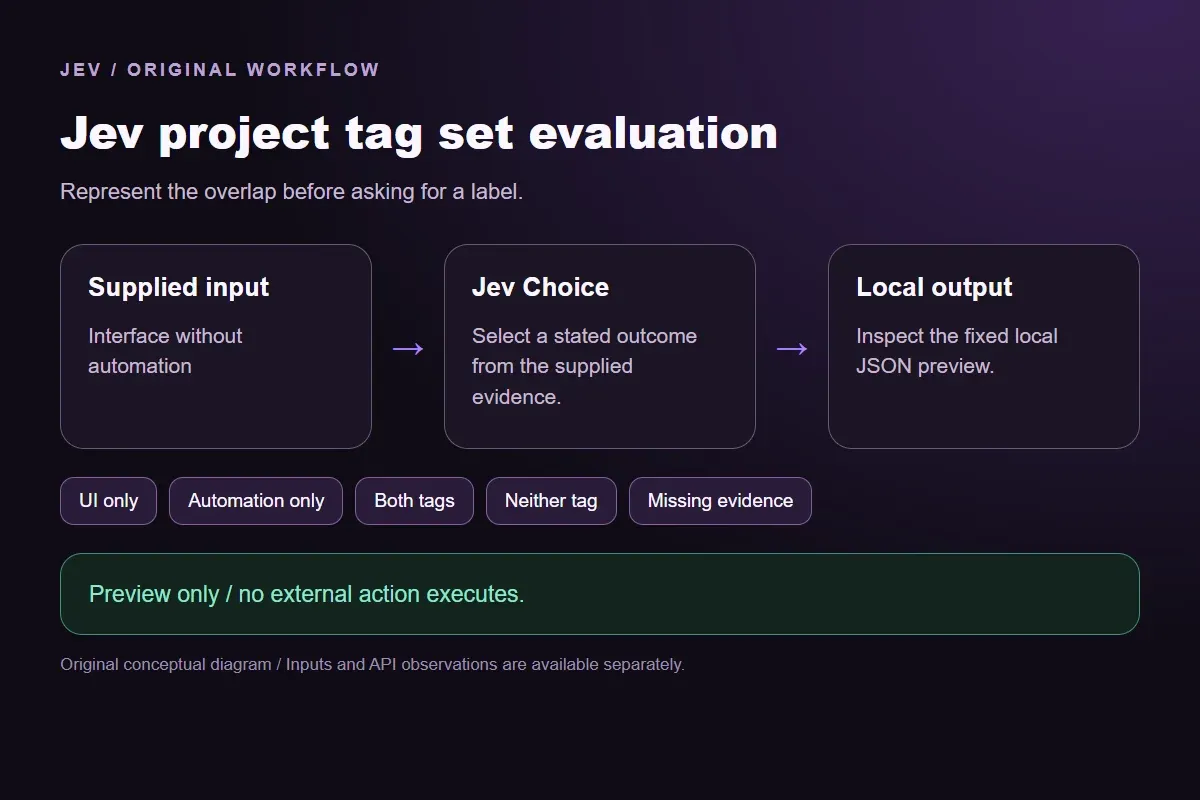
Jev project tag set evaluation checks two attributes in a supplied implementation description: a human-facing interface and an unattended workflow. A project can have either, both or neither. Our original question includes those complete tag sets as separate choices, so overlap is representable instead of being lost in a forced single-category result.
An API-collected X post described a category classifier using eight independent yes/no questions and an ambiguous project. That inspired this smaller contract exercise. We do not reproduce its classifier or claim that one Choice performs those eight independent questions. Here there are only two tags, and the four complete sets plus Missing evidence are explicitly enumerated.
The local consumer maps a selected outcome to a fixed tags array. The array is application data, not model-generated JSON. Both tags returns ui and automation together; Neither tag returns an empty array; missing implementation evidence stays pending. That output boundary makes it clear what the model decides and what the program serializes.