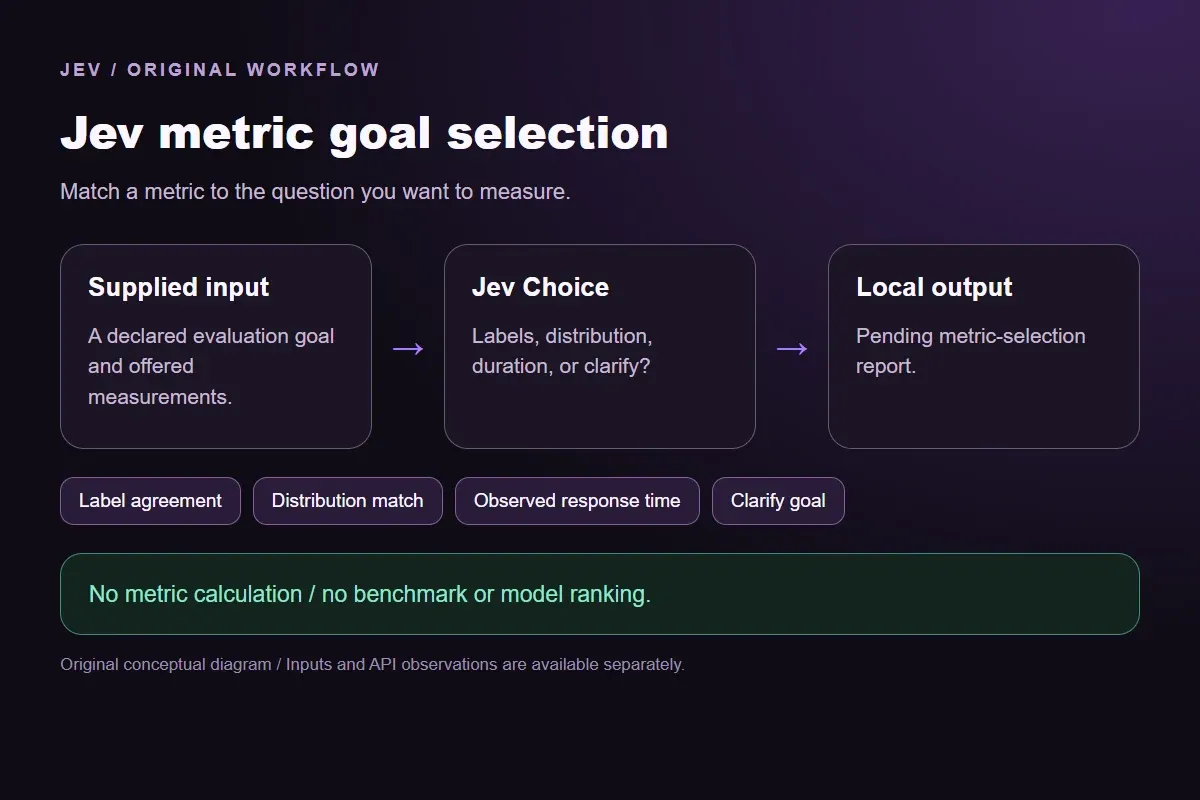
Jev metric goal selection maps a stated evaluation question to an explicitly offered measurement. The window distinguishes agreement with reference labels, match to a reference probability distribution and elapsed request time. It leaves missing, compound or unsupported goals unresolved rather than inventing a benchmark score.
The API-collected source mentions accuracy and distribution metrics in a model comparison. This original demonstration asks which measurement addresses a goal; it does not repeat those numbers, reproduce the benchmark or rank Jev against another model. The goals and references are synthetic descriptions.
Different metrics answer different questions. Choosing a metric does not establish that the reference is independent, the measurement is correctly implemented or the test represents a future workload. The output is a pending selection report. A real evaluation still needs actual data, a declared protocol and independently checked calculations.