Useful scope
- Choosing a semantic role among already extracted spans
- Testing missing-total and reordered candidates
- Keeping exact value handling in ordinary code
Use the surrounding wording to select one pre-parsed amount identifier, leaving exact copying and arithmetic to code.
The same numeric value can appear under a different candidate identifier. The model reads the surrounding wording and chooses the identifier whose span is explicitly total due. A consumer can then copy that stored span unchanged.
The missing-total fixture supplies numbers that could tempt a calculation. The rule forbids that calculation and requires None of these when no supplied candidate is labeled total due. Exact arithmetic belongs in ordinary code.
The source mentions replacing regex-heavy parsers, while the official TypeSafe cookbook explains pre-parsed span selection. This original demo uses fixed fictional candidates; it does not parse a live invoice or initiate payment.
These fictional inputs and decision rules were written for this page. The linked X discussion provides background; the technical implementation follows TypeSafe's Choice contract.
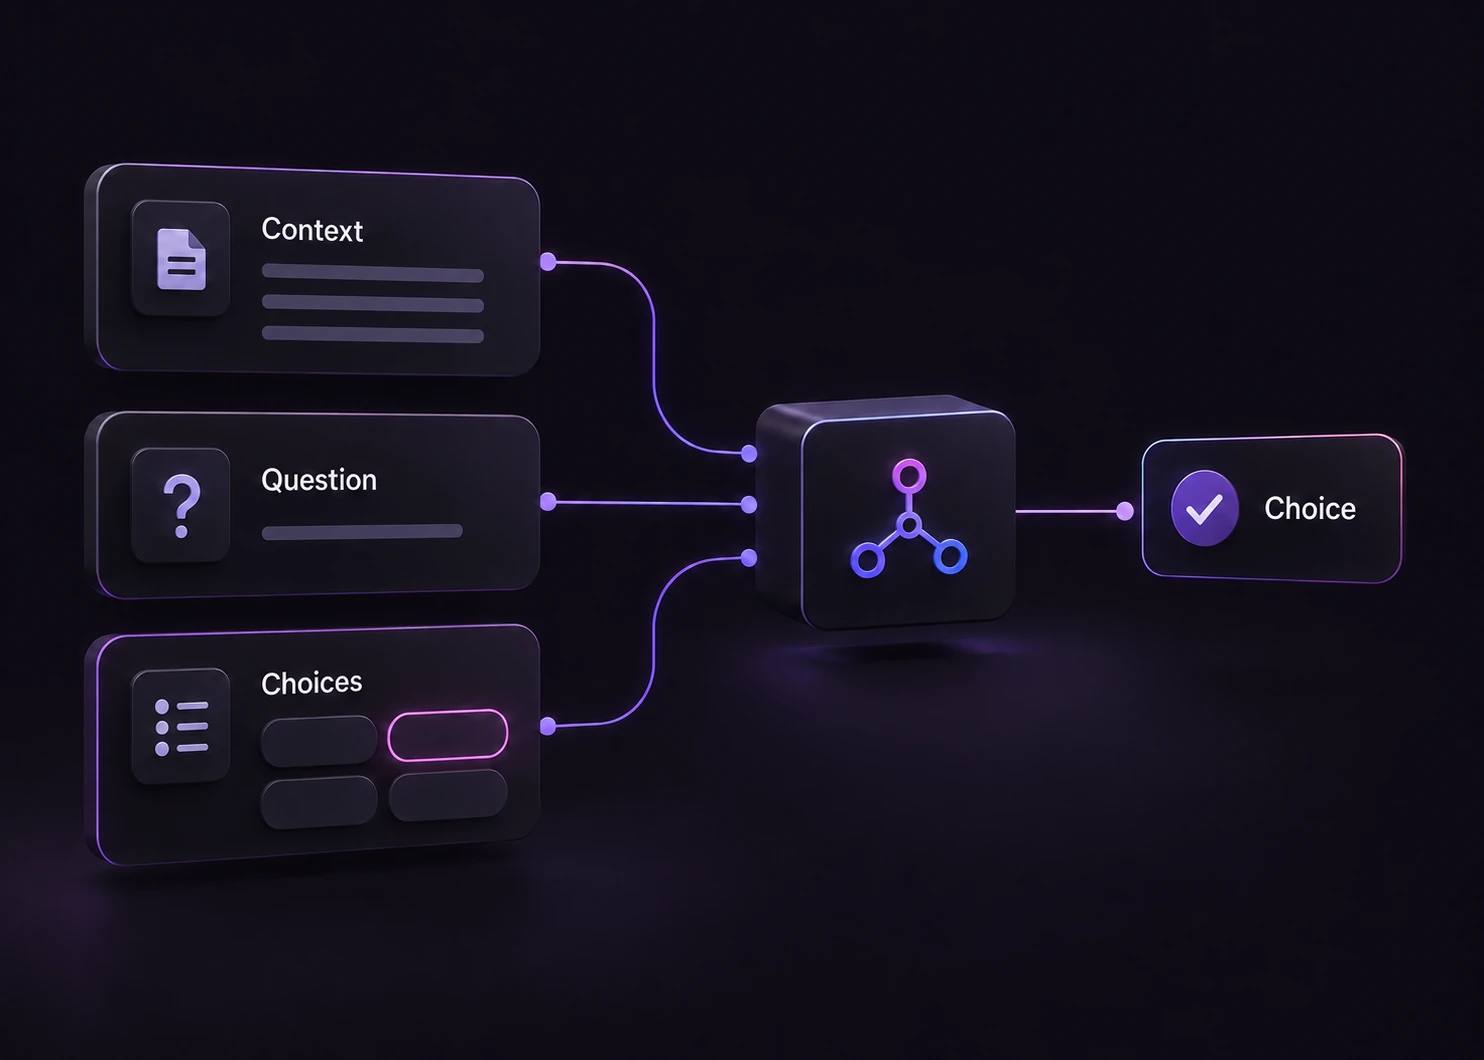
Use the supplied facts to inspect one bounded decision before connecting it to a larger workflow.

Supply the extracted candidate IDs, exact spans and surrounding invoice wording. Extraction and structural validation should happen before this semantic selection.

The decision rule and the choice labels are sent with the evidence. Keep Need evidence available when required facts are missing. A strong leading probability cannot supply a hidden fact.

The window makes a fresh server-side API request. It displays the highest-probability label, elapsed request time and estimated token cost. A provider failure produces an error, not a missing-evidence label.

Preview a candidate identifier. Code must validate the identifier and copy the original span; no payment or amount calculation occurs. Download the requests and saved observations. The offline consumer validates their hashes and prints a pending packet without executing it.
| Original input | Observed label | Leading probability |
|---|---|---|
| A is payable | Candidate A | 100% |
| B is payable | Candidate B | 100% |
| C is payable | Candidate C | 99.0% |
| No total stated | None of these | 99.0% |
| Do not calculate a missing total | None of these | 99.0% |
| Candidate list absent | Need evidence | 100% |
These are six original synthetic inputs, tested once per request revision. The percentage is the leading option probability, not measured accuracy. Authored expectations and any disagreements remain in the downloadable evidence. 6 of 6 results matched the authored fixture expectations.Verified
Compare each saved result with its authored expectation. A disagreement remains in the fixture review; the call is not repeated to obtain a preferred label.
The single-request SDK runner uses your private TYPESAFE_API_KEY. The offline consumer reads saved observations, checks request hashes and prints a pending output. It does not call the model or change any external system.
npm install @typesafe-ai/sdk@0.6.0
# Set TYPESAFE_API_KEY privately in your shell.
node run-choice-sample.mjs samples.json case-1
python preview_choice_workflow.py samples.json saved-api-results.jsonThe rubric explains the decision; the application owns the next step.
No. It is an identifier for a span already supplied by the caller. The model does not calculate or rewrite the amount.
Keep None of these available. Improve the extraction step or request more evidence instead of making the model invent a candidate.
No. It is the model distribution for this one request. The six examples are functional checks with authored expectations, not a representative benchmark. Inspect disagreements and evaluate your own examples before using the label.
The window shows an error and supplies no fresh judgment. The downloadable runner sends one request without retries. Need evidence is a valid outcome about incomplete input; it does not stand in for a network or provider failure.
Edit the evidence above or use the Playground to test another bounded question.