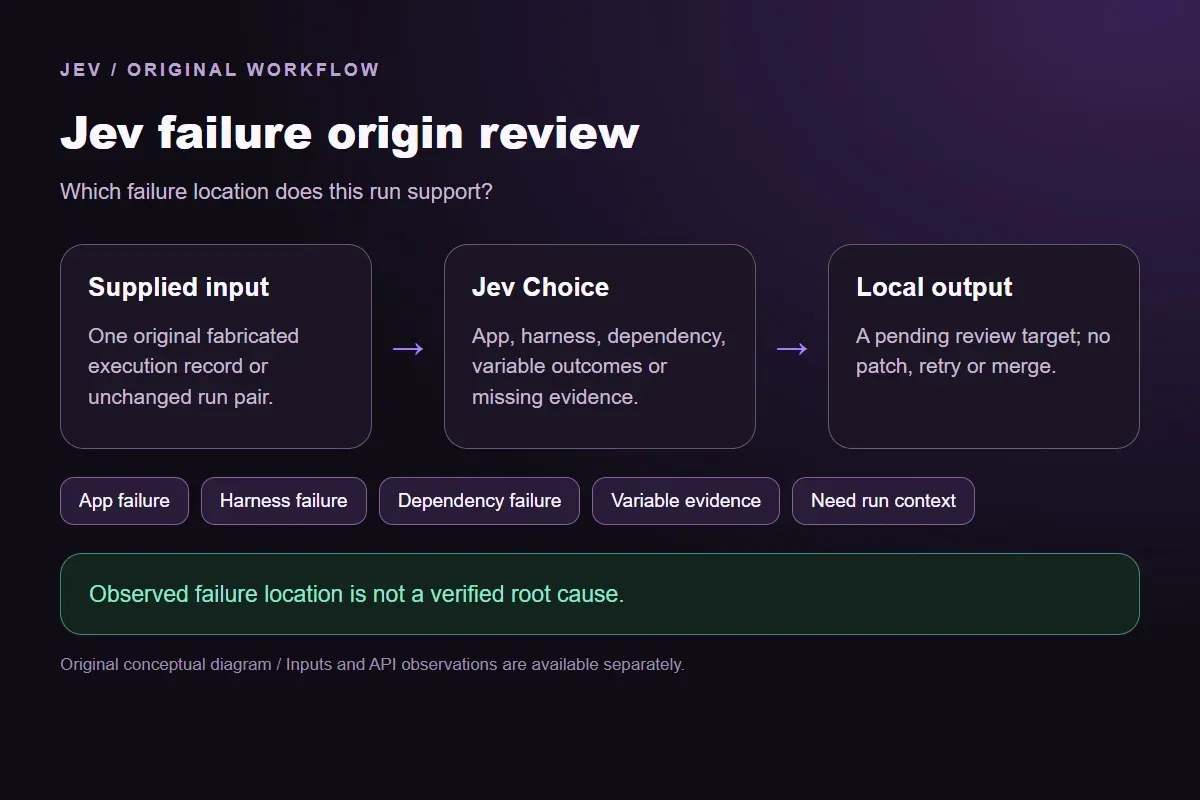
Jev failure origin review locates the failure supported by a supplied run record. Jev separates an observed application failure, a harness failure before invocation, an explicit dependency failure, variable outcomes and missing context. The output proposes which evidence an operator should review next.
A red test result alone does not identify the failed component. The original fixtures describe whether the runner reached the application, what the observed output was and whether an external prerequisite was available. The model reads those supplied facts; it does not execute tests or investigate a live repository.
An API-collected coding-agent post proposed separating bugs, flaky runs and environment problems. It inspired this more conservative evidence-based classification. We do not reproduce its video, claimed speed, spending limits or automatic merge rule. Inconsistent outcomes remain variable evidence rather than a claimed diagnosis of flakiness.
Start with the missing CSV field and the malformed fixture. Both are failures, but only one supplies an observed app result. Then compare the unavailable dependency and the unchanged run pair. All records are fabricated, and each label maps to a pending local review step rather than a retry, patch or merge.