Useful scope
- Reducing obvious common-word matches in a review queue
- Testing brand-versus-product references with an explicit profile
- Keeping ambiguous names visible for further review
The same word can name a company or an ordinary object. Inspect the words in a domain label before adding it to a brand-review queue.
Shared words make simple substring matching noisy. The brand profile provides the product context, while the domain label supplies clues about which meaning is intended.
The source describes separating name interpretation from later domain-review steps and leaving the top-level suffix out of this judgment. Our examples use fictional brands and labels. A brand reference can describe a fan discussion, repair service or something else; it is not a finding of abuse.
This is an independently authored text demonstration inspired by the linked X discussion. Its rules and synthetic inputs are ours. It does not reproduce the author’s application, verify reported outcomes, or perform an external action.
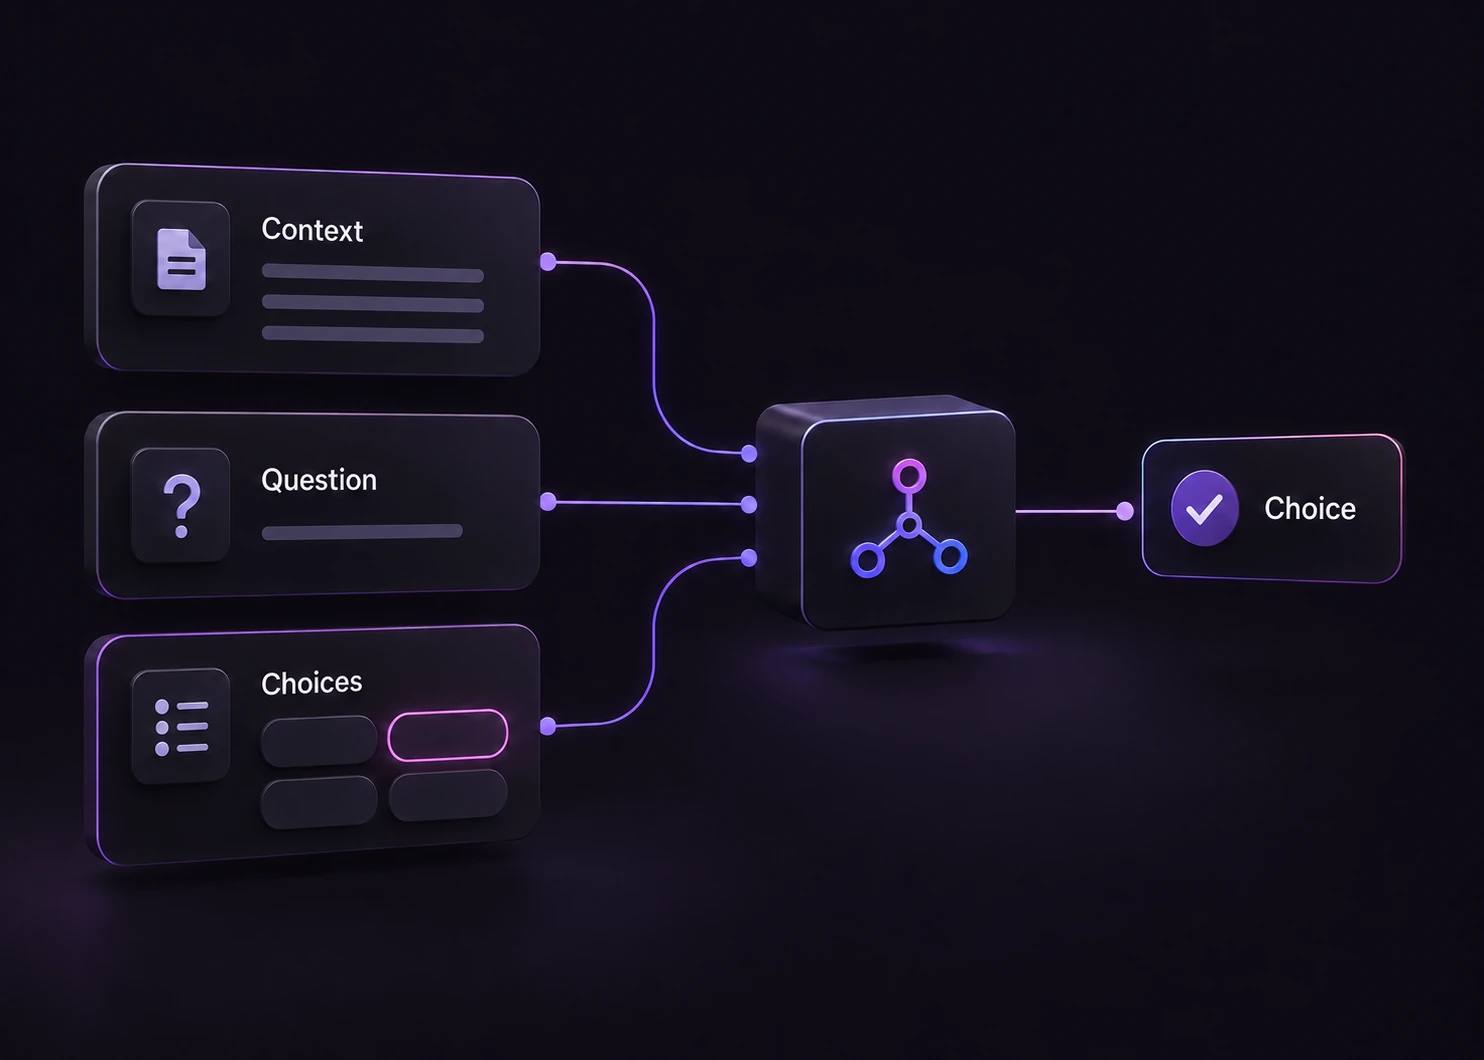
Change the evidence, inspect the available labels, then compare the response with the rule.

Use the named fields in the sample. Include the context that distinguishes the outcomes; leave absent facts explicitly unknown.

The decision rule and the choice labels are sent with the evidence. Read the definitions before changing the labels. The model chooses among these supplied alternatives.

The window makes a fresh server-side API request. It displays the highest-probability label, elapsed request time and estimated token cost. A provider failure produces an error, not a missing-evidence label.

Treat the returned label as a proposal. Check the evidence and distribution before consuming it in application code. Download the requests and saved observations. The offline consumer validates their hashes and prints a pending packet without executing it.
| Original input | Observed label | Leading probability |
|---|---|---|
| Named product | Brand reference | 99.0% |
| Fruit growing | Common meaning | 95.0% |
| Different topic | No reference | 94.0% |
| Bare shared word | Brand reference | 66.0% |
| Discussion group | Brand reference | 99.0% |
| Food topic | Common meaning | 99.0% |
These are six original synthetic inputs, tested once per request revision. The percentage is the leading option probability, not measured accuracy. Authored expectations and any disagreements remain in the downloadable evidence. 5 of 6 results matched the authored fixture expectations. For Bare shared word, the expectation was Review; the observed choice was Brand reference.Verified
The downloads contain six original inputs, their expected labels and one recorded API observation per input revision. Disagreements stay visible.
The single-request SDK runner uses your private TYPESAFE_API_KEY. The offline consumer reads saved observations, checks request hashes and prints a pending output. It does not call the model or change any external system.
# Offline: inspect the downloaded saved observations. No API key is needed.
python preview_choice_workflow.py samples.json saved-api-results.json

# Optional live request: install the SDK and set TYPESAFE_API_KEY privately.
npm install @typesafe-ai/sdk@0.6.0
node run-choice-sample.mjs samples.json case-1
# The live response prints to the terminal; it does not update saved-api-results.json.The input contract and these limits define what the result means.
No. The label only describes what the wording appears to refer to. Ownership, permission, use and legal questions require separate evidence and review.
This question concerns the name's meaning. The application can parse the domain and provide its label; the suffix should not act as a shortcut for a legal or safety conclusion.
It describes the distribution over the supplied choices for this request. These six synthetic examples are functional tests with authored expectations, not a production accuracy benchmark.
No. The demo displays a label and distribution. The downloadable consumer produces a pending preview packet. Application code and a separate authorization policy would control any real action.
Edit the example above to see how a changed fact affects the decision, or open the Playground for another task.