Jev decision contract coverage

Jev decision contract coverage. Check that the answer space covers the actual issue.

Jev decision contract coverage: Checks whether the offered outcomes can represent the user issue before another decision attempts to choose among them.

Check that the answer space covers the actual issue.Live API
Try an example

Original synthetic input. Edit the task or evidence to make a new API request.

Source: Workflow inspiration on X

Source and example scope

The inputs, rubric and preview are original. This window demonstrates the stated decision only; it does not reproduce the source application or its measurements.

Review the decision contract for this user issue.

Decision rules and labels
CoveredMissing outcomeAmbiguous contractMissing issue
A real response from the Jev API

Edit any input to explore a different decision. No request is sent until you run it.

Your next decision

Not run yet

Choose an example or write your own input, then run it to see the ranked choices.

Results are not stored by this site. Your submitted text is processed by the API provider.

The decision

How does Jev decision contract coverage use its evidence?

Jev decision contract coverage checks whether the offered outcomes can represent the user issue before another decision attempts to choose among them.

The source post explains why a valid enum can still produce a wrong workflow decision. Our original contracts examine one specific cause: an outcome vocabulary that fails to represent the user issue. No payment record, refund permission or settlement lookup is accessed. The fixture checks coverage before a separate operational question is answered.

Typed output restricts the response vocabulary. That property helps a consumer parse the result, but the vocabulary must first cover the issue. Here Jev evaluates the supplied contract itself. A Covered result means a relevant outcome exists; it does not declare that the outcome will be selected correctly in a later operational call.
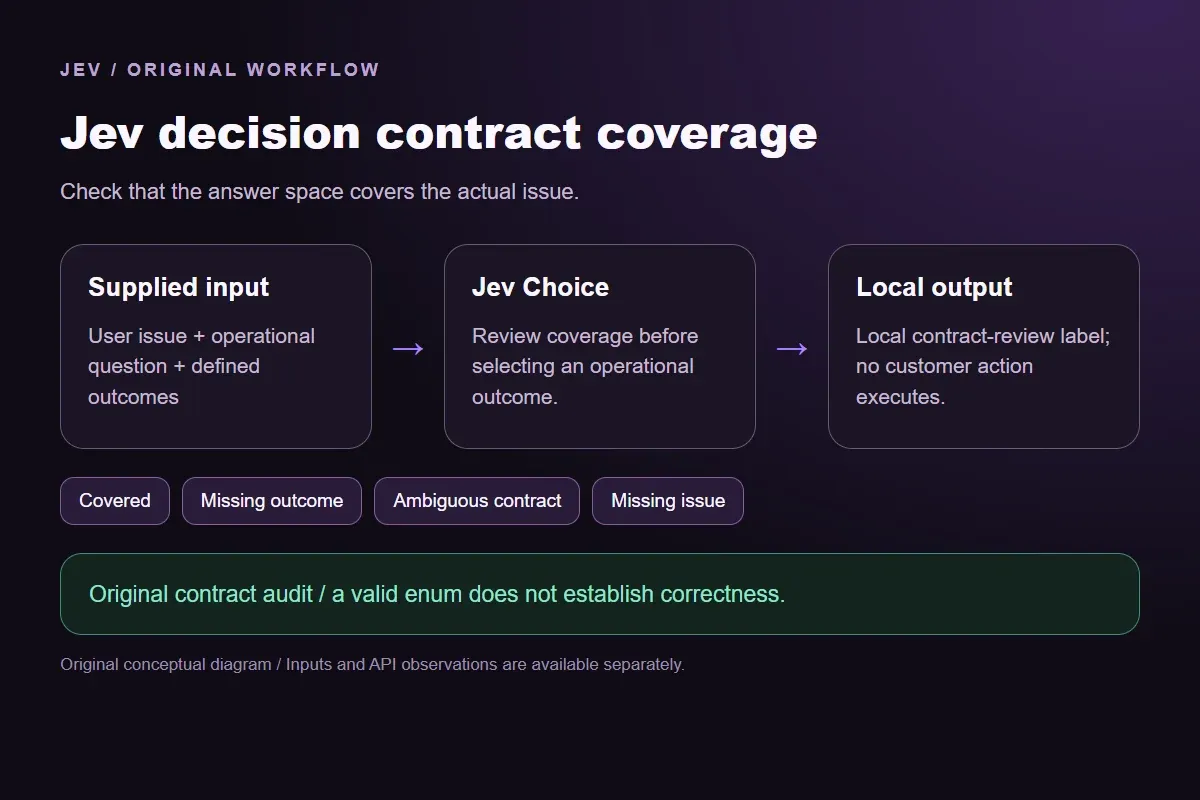

Original Jev decision contract coverage workflow diagram showing supplied evidence, a typed decision and the local preview.
Original workflow illustration. The output is a local preview, not an executed action or source screenshot.
How it works

Inspect the decision in four steps.

Keep the evidence and the returned output attached to the same request.

  1. Illustration of adding the text or evidence for a decision

    Supply the actual task

    Issue: refund approved, money not received. Question: should refund be approved? Outcomes: approve, deny, review approval eligibility only. The model sees this original task and the provided evidence.

  2. Illustration of defining a question and its allowed choices

    Define the permitted outcomes

    Use the explicit rubric in the window. Every label has a stated meaning; missing evidence cannot create an unavailable action.

  3. Illustration of sending one input and comparing the returned choices

    Inspect the complete response

    Compare all offered probabilities and preserve the actual leading choice. A provider failure is separate from a semantic no-match or review outcome.

  4. Illustration of reviewing a result and an uncertain item before using it

    Preview the local handoff

    Replay the saved observations with the offline consumer. The mapped JSON stays local and no external action executes.

Our API test

What the six original inputs returned.

What the six original inputs returned.
Original test inputFixture expectationObserved labelLeading probability
An approval question for a settlement problemMissing outcomeMissing outcome59%
A relevant settlement outcomeCoveredCovered86%
Unexplained outcome meaningsAmbiguous contractAmbiguous contract68%
No actual support issueMissing issueMissing issue100%
A cancellation vocabulary for address correctionMissing outcomeMissing outcome95%
A vocabulary that covers address correctionCoveredMissing outcome58%
  • 5 of 6 original fixture expectations matched. Contrary outputs are preserved in the table and downloads; these checks are not held-out accuracy or production suitability.
  • Measured adapter round trips: 483-1324 ms. Estimated input cost: $0.00002163-$0.00002197 per request. These observations are not a latency guarantee or invoice.

6 actual Jev API calls on October 1, 2026. Original synthetic inputs check this rubric and handoff; they do not establish held-out accuracy. Probabilities are model outputs.Verified

How can you reproduce this decision and inspect its output?

Original example note 1

The settlement fixture describes an already approved refund whose money has not arrived. Its operational question only concerns approval eligibility. Missing outcome identifies that mismatch without trying to reverse or repeat the approval. The preview does not fetch a payment status; it tells the contract author why a different question is needed.

Original example note 2

The complete fixture offers fetch settlement status as a next support step. That outcome can represent the stated issue, so the original expectation is Covered. This does not validate the settlement service, its authentication or its answer. It checks that the decision space contains a relevant step before a separate call chooses one.

Original example note 3

The vague fixture uses A, B and C without definitions. Ambiguous contract preserves the missing label semantics. An enum can be syntactically valid while its choices remain unintelligible. Supplying the definitions would change the contract and require a new response; a guessed meaning should not become an undocumented policy.

Original example note 4

The absent-issue fixture gives a question and plausible support outcomes without an actual customer problem. Missing issue separates that omission from a known issue whose handling is absent. The demo cannot assess coverage for a request that has not been supplied, and its local preview has no customer-specific recommendation.

Original example note 5

The cancellation fixture tests another domain boundary: correcting a street is a different issue from deciding whether to cancel. The choices explicitly concern cancellation policy only. Missing outcome should preserve the need for an address-edit step. The classifier is reviewing coverage rather than accepting or denying the customer request.

Original example note 6

The address fixture adds verify edit window as a relevant step. Its original expectation is Covered, but the recorded leader was Missing outcome at 58%. The model did not agree that this preliminary check adequately covered the issue. That disagreement remains in the table and downloads; the demo does not replace the answer with its expectation. Edit permissions and dispatch status still require separate application evidence.

Original example note 7

Five of six original fixture expectations matched. The address-edit contract returned Missing outcome at 58% instead of the expected Covered. The complete distribution remains unchanged. This is a contract-review teaching fixture, not proof that the model reliably certifies operational coverage.

Original example note 8

Download the exact sample requests and saved observations below. Expected labels are original fixture checks and stay outside the request sent to Jev. The observation file preserves the complete probabilities and the hash of each exact request. Editing a task, rubric or candidate requires a fresh response; a matching sample name does not make an older answer current.

Original example note 9

The JavaScript runner makes one independent SDK request for a chosen sample ID. It reads TYPESAFE_API_KEY privately from the environment and has no automatic retry. The Python consumer operates offline: it checks the rubric, labels, unique sample identities, request hashes and valid probability distributions before selecting a fixed local preview. A tied leading result remains pending for review.

Original example note 10

The page reports measured adapter round trips and estimated input cost for the recorded calls. Those values describe these requests, not a provider latency guarantee or a billing statement. Six deliberately authored fixtures can check the stated behavior, but they do not establish accuracy on an unseen dataset. Keep disagreements and missing-input examples when testing an integration.

How can you reproduce this decision and inspect its output?

Runnable offline example

Replay one request and inspect the saved preview.

View the code example
Replay commands
npm install @typesafe-ai/sdk@0.6.0
# Set TYPESAFE_API_KEY privately in your shell.
node run-choice-sample.mjs samples.json settlement
python preview_choice_workflow_v2.py samples.json saved-api-results.json
Scope of this demo

Where does this decision fit?

Useful with explicit supplied evidence

  • Review whether a supplied decision question and outcome vocabulary can represent the actual user issue, rather than classifying that issue into a vocabulary with missing outcomes. Original decision-contract examples only; no refund or payment is executed.
  • Inspecting the original task and a fixed output before integrating external tools.
  • Comparing an explicit expected label with the complete recorded distribution.

Needs separate implementation or evidence

  • Inferring facts absent from the supplied input.
  • Treating a semantic selection as authorization to act.
  • Executing an external action or generalizing six fixtures into an accuracy claim.
Example FAQ

Questions about this original decision workflow.

Keep relevance, compliance and execution separate.

What does label coverage review evaluate?

It checks whether a supplied question and outcome vocabulary can represent the actual issue.

Does Covered mean the future operational answer is correct?

No. It means a relevant outcome is available. Selection accuracy and action authorization remain separate.

Can Jev invent a missing fourth outcome?

This demonstration returns only its offered review labels. A contract author must add the operational outcome in a separate revision.

Why distinguish a missing issue from missing coverage?

Coverage cannot be judged without an issue. Missing outcome requires a clear issue that the stated vocabulary fails to handle.

Does this demo query settlement records?

No. All support situations and decision contracts are original text fixtures.

Try a task from your own workflow

Change the supplied task or evidence here, then inspect the live response. Playground supports another explicit decision.


