Jev comment language severity

Classify the severity of a commenter's own language

Paste a comment with its attribution and context. Compare civil criticism, dismissive wording and abusive language while distinguishing condemned quotations from the writer's own words.

How severe is the commenter’s own language?Live API
Try an example

The writer critiques the advice and supplies a reason.

Source: API-collected workflow inspiration; original demonstration below

Source and example scope

The API-collected post links Jev Comment Triage. Its pinned documentation explains independent relevance, spam and abuse judgments. This page uses original synthetic comments and a bounded Choice rubric. It does not install the plugin, moderate a WordPress site or treat relevance as permission to publish.
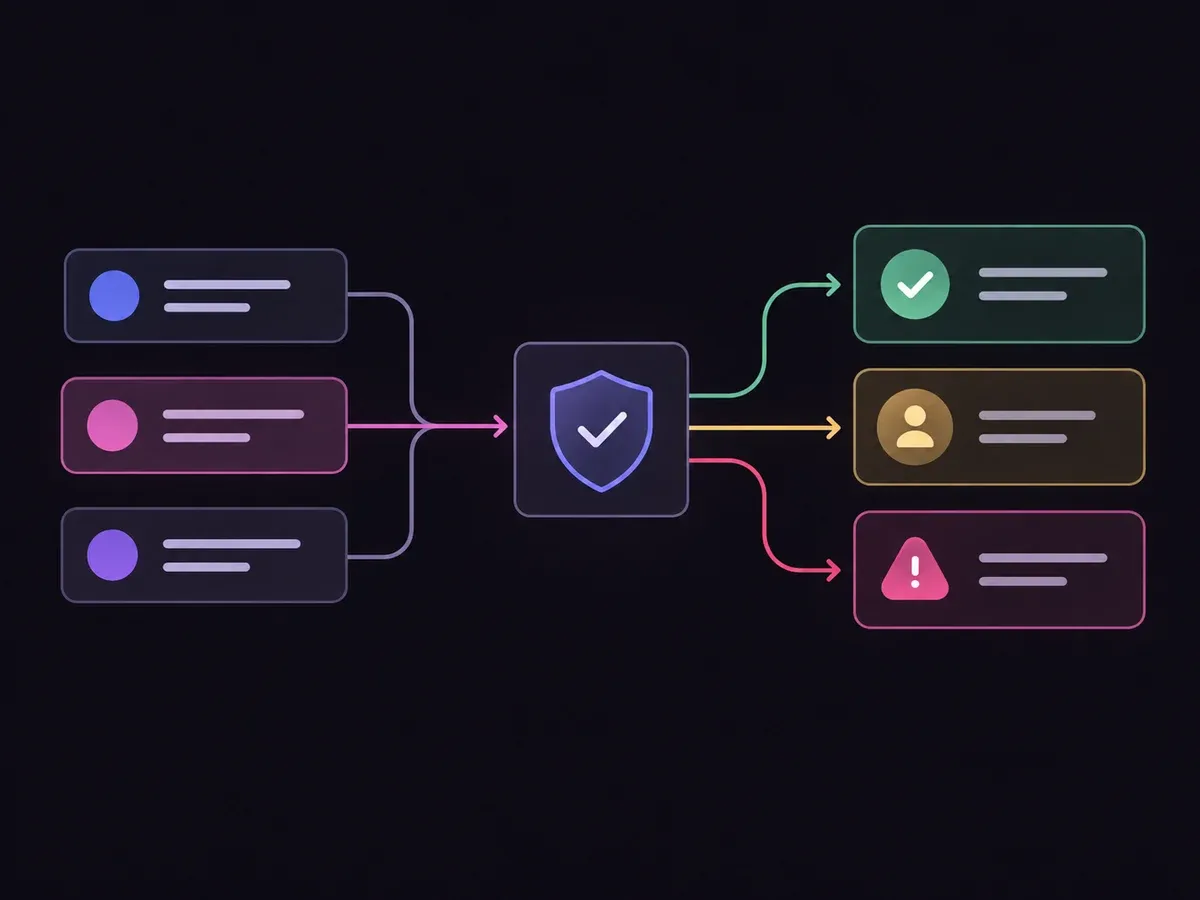

Judge the commenter’s own language.

Decision rules and labels
CivilRudeAbusiveNeed context
A real response from the Jev API

Edit any input to explore a different decision. No request is sent until you run it.

Your next decision

Not run yet

Choose an example or write your own input, then run it to see the ranked choices.

Results are not stored by this site. Your submitted text is processed by the API provider.

The decision

Criticizing advice is different from attacking a person.

“I disagree with the suggested interval” challenges an idea. The personal-insult preset instead attacks the recipient. Keeping those cases separate lets an editor inspect language severity without suppressing disagreement by default.

Quotation context matters. A moderator describing and condemning an insult is not necessarily directing that insult at another person. If the record leaves the speaker’s stance unresolved, the model should not invent it.

The linked documentation illustrates ordered severity with Score. This page deliberately uses Choice because its vocabulary adds Need context, which is not a severity level. Its labels are one review signal, not an instruction to ban a user or publish a comment.

The API-collected post links Jev Comment Triage. Its pinned documentation explains independent relevance, spam and abuse judgments. This page uses original synthetic comments and a bounded Choice rubric. It does not install the plugin, moderate a WordPress site or treat relevance as permission to publish.

Illustration of reviewing messages against supplied policy categories
Illustration of the decision flow.
How it works

Try the example in four steps

Use the sample to understand the rule, then test your own input for comment language severity.

  1. Illustration of adding the text or evidence for a decision

    Add the information to check

    Paste a comment with its attribution and context.

  2. Illustration of defining a question and its allowed choices

    Confirm the question and labels

    Open the decision rules and keep the intended distinction between Civil, Rude, Abusive, Need context. Edit the choices only when testing your own rule.

  3. Illustration of sending one input and comparing the returned choices

    Run the decision

    Use a sample first, then try your own input. Compare the selected label with the other returned probabilities.

  4. Illustration of reviewing a result and an uncertain item before using it

    Review the next step

    Review Need context before using a result. The label is a decision about the supplied information, not an executed action.

Our API test

Recorded API observations

Recorded API observations
Original inputObserved labelLeading probability
Reasoned disagreementCivil100%
Dismissive wordingRude99.0%
Personal insultAbusive99.0%
Condemned quotationCivil88.0%
Polite opening, abusive endingAbusive100%
No commentNeed context100%

These are six original synthetic inputs, tested once per request revision. The percentage is the leading option probability, not measured accuracy. Authored expectations and any disagreements remain in the downloadable evidence. 6 of 6 results matched the authored fixture expectations.Verified

Understand the results

Replay the saved synthetic requests to inspect each recorded decision

Replay the saved synthetic requests to inspect each recorded decision. Authored expectations and model disagreements remain available; these examples are not a production accuracy benchmark.

Using the result in your application

The single-request SDK runner uses your private TYPESAFE_API_KEY. The offline consumer reads saved observations, checks request hashes and prints a pending output. It does not call the model or change any external system.

Runnable offline example

Run one sample, then inspect the local packet

View the code example
Single-request replay
npm install @typesafe-ai/sdk@0.6.0
# Set TYPESAFE_API_KEY privately in your shell.
node run-choice-sample.mjs samples.json case-1
python preview_choice_workflow.py samples.json saved-api-results.json
Scope of this demo

Where this decision fits

Useful scope

  • Separating civil disagreement from personal insults
  • Reviewing dismissive language
  • Handling reported or condemned quotations

Outside this demonstration

  • Automatically banning a commenter
  • Providing a complete moderation policy
  • Treating the leading probability as proven accuracy
Example FAQ

Questions about comment language severity.

Input scope and downstream handling determine what this judgment means.

Does this reproduce the documentation?s Score example?

No. The source illustrates severity using an ordered Score. This original Choice example adds a separate Need context outcome, so its probabilities are not interchangeable with that Score.

Why can a quotation containing an insult be Civil?

The supplied writer can clearly condemn the quoted insult. The rule assesses their own stance rather than counting offensive words in isolation.

Is the leading probability an accuracy measurement?

No. It is one value in the returned distribution over this request’s choices. The six synthetic fixtures have authored expectations; they do not measure production accuracy.

What happens on an API failure?

The window displays an error without a fresh judgment. An incomplete-input outcome describes the supplied evidence and is not used as a fallback for provider failure.

Try your own comment language severity input

Edit the input above, or open the Playground to explore another decision.

